This BLOG focuses on "hands on approach" around AWS, OCI Oracle Cloud Infrastructure, Dev/Ops, MicroServices, OKTA, Oracle Fusion Middleware, Oracle Service Bus, Oracle AIA, Oracle SOA Suite, Oracle SOA Cloud/Developer Cloud, Oracle Identity Management including OID, OAM, OIM, OSSO, Oracle Big Data, WLST Scripts and Oracle Edifecs B2B Engine for HIPAA/HL7/X12/EDIFACT EDI., Kafka, Spark, Spring Boot, DevOps, AWS, GCP and Oracle Cloud
Oracle Event Hub Cloud Service delivers the power of Kafka as a managed streaming data platform integrated into the Oracle Cloud ecosystem. Create Topics and start streaming or manage and deploy your own Dedicated Kafka Cluster with Elastic Scalability.
Perform the following steps to create an Oracle Event Hub Cloud Service - Topic instance. You can skip this section, if you already have an Oracle Event Hub Cloud Service - Topic instance and plan to use that for this demo.
Log in to your Oracle Event Hub Cloud Service - Topic account.
In the Services page, click Create Service.
The Create Service screen appears. Provide the following details and click Next.
Service Name: topicdemo
Service Description: Example to demo topic
Hosted On: platformdemo
Number of Partitions: 2
Retention Period (Hours): 24
Note: The platformdemo is the name of the Oracle Event Hub Cloud Service - Platform cluster in which the topic will be created. You can provide a different name if you want to host this in a different Oracle Event Hub Cloud - Platfrom cluster.
In the Confirm page, if you find the details appropriate, click Create.
The control returns to the Services page. In the Services page, you could now see the new topicdemo service listed.
Click on the Event Hub icon adjacent to the topicdemo instance to go to the Service Overview page.
In the Service Overview page, observe the Topic field. This is the name of the Topic service that will be used in programs demonstrated in this tutorial.
Kafka is a publish-subscribe messaging system that provides a reliable Spark Streaming
source. The Kafka project introduced a new consumer API between versions 0.8 and 0.10, so there are 2 separate corresponding Spark Streaming packages available. The API provides one-to-one mapping between Kafka's partition and the DStream generated RDDspartition along with access to metadata and offset.
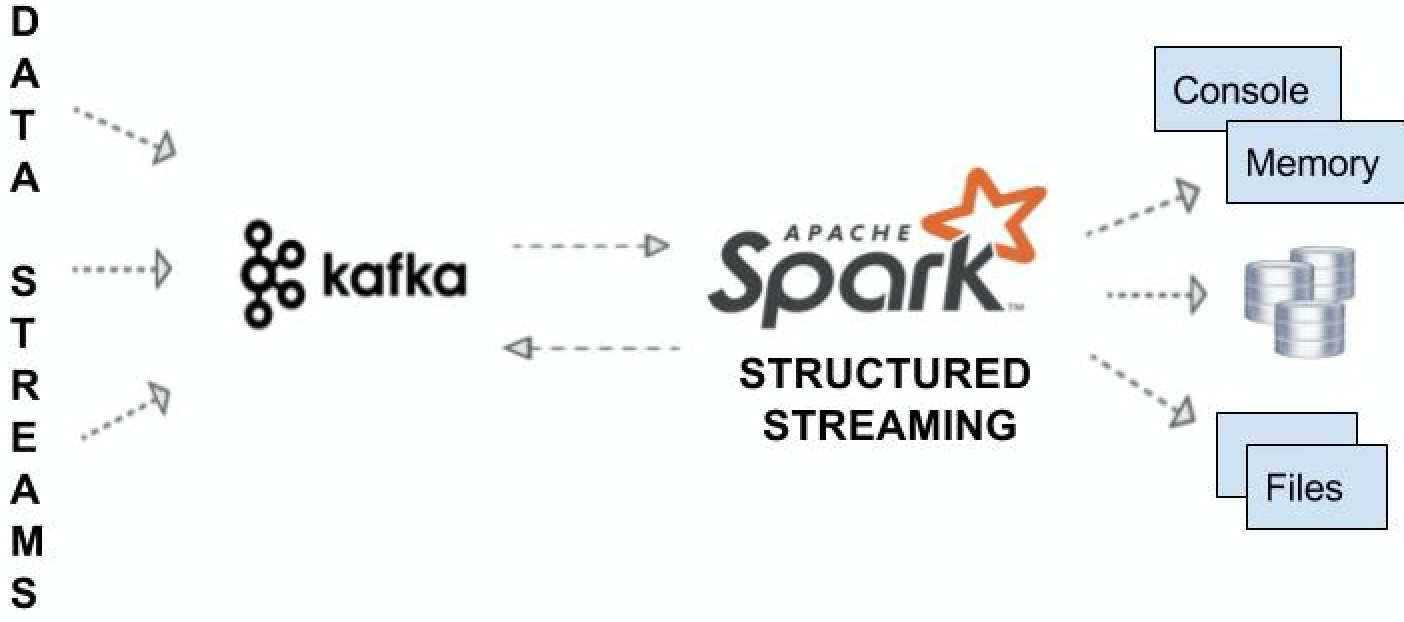
The following diagram shows end-to-end integration with Kafka, consuming messages from it, doing simple to complex windowing ETL, and pushing the desired output to various sinks such as memory, console, file, databases, and back to Kafka itself.
Following set of properties will need to be added to Spark Streaming API to integrate Kafka with Spark as a Source
bootstrap.servers: This describes the host and port of Kafka server(s) separated by a comma.
key.deserializer: This is the name of the class to deserialize the key of the messages from Kafka.
value.deserializer: This refers to the class that deserializes the value of the message.
group.id: This uniquely identifies the group of consumer.
auto.offset.reset: This is used messages are consumed from a topic in Kafka, but does not have initial offset in Kafka or if the current offset does not exist anymore on the server then one of the following options helps.
When a project is created, you can choose to initialize the project with one project Git repository for the project. A Maven repository is also created. If required, you can add more project Git repositories, external Git repositories, import Git repositories, and configure auto-cleanup of the to the project Maven repository.
This BLOG discusses steps to create the GIT repository :-
Login to the Oracle Developer Cloud Services
and Select Create New Project.
Click
Next
Choose
the option to create a Empty Project
Choose Wiki Markup as Mark Down
A few seconds of provisioning later the Project will be accessible – navigate to the Code Section of the Developer Services Project and hit the New Repository button. This will start the process to create a new git repository. Make sure not to initialize it, but simply create an Empty Repository.
Default SOA settings do not allow to view SOAP
message (header & body)out-of-the-box on the EM Console
or in the logs.
In order to see these SOAP
conversations for a SOA composite service you can follow below steps: Please
note the log file to be checked is OWSM
Using
the Enterprise Manager, attach the management policy named oracle/log_policy to
the webservice reference to which the SOAP headers needs to be monitored.
Restart
the composite
Check
the below log file to view the SOAP messages whenever the webservice call
is made.$DOMAIN_HOME/domain_name/servers/mserver_name/logs/owsm/msglogging/diagnostic.log
This BLOG thread discusses the steps on deployment of MDS artifacts on SOA cloud instance.
Setup JDeveloper SOA_DesignTimeRepository
JDeveloper 12.2.1 or 12.2.1.2 by default creates the SOA_DesignTimeRepository. This is a file based repository. At MindTelligent, we link this directory to SVN or GIT master repository. It is imperative that we have a main folder /apps and all the artifacts are stored under the apps folder.
On looking at the Design Time Repository closely, the structure looks like as shown below:
To change the location of the directory, simply right click on the SOA_DesignTimeRepository, and click on Properties.
Please click on the Browse button and choose the folder you wish to select as File based Repository
Please note that you do not select the /apps folder under which all the artifacts are located.
That is it for JDeveloper Setup. You are ready to build your composites.
Deploy the MDS artifacts on SOA cloud
Log in to your SOA Cloud Instance
Navigate to the "SOA Fusion Middleware Control Console"
Navigate to SOA Infrastructure-->Administration-->MDS configuration
Choose the option to Import the MDS
Please navigate to the folder where the Zip file for the SOA_DesignTimeRepository is located. The zip file SHOULD include the /apps folder
EM will display the following message if all the artifacts are successfully uploaded to the MDS: